ZCode Agentic Development Environment: GLM-5.3 Architecture, 25M Free Tokens, and Benchmark Analysis
ZCode brings GLM-5.3 into an Agentic Development Environment with 1M context, 25M free trial tokens, 84.5% CyberGym defense, and 28.3% Terminal Bench score.

Synthesizing article benchmarks & model metrics...
Z.ai (the international entity of Zhipu AI) has launched ZCode, a native desktop Agentic Development Environment (ADE) built around its frontier foundation model, GLM-5.3.
Unlike autocomplete plugins or sidebar chat widgets that simply provide code snippets on demand, ZCode is architected for autonomous goal execution: planning multi-file refactors, modifying codebases, executing terminal shell commands, parsing compiler diagnostics, and iterating until tests pass.
To drive developer adoption, ZCode provides new users with 25 million free promotional tokens—allocated as 5 million tokens daily for 5 days (3M GLM-5.3 + 2M GLM-5-Turbo tokens per day) with zero credit card commitment required.
Technical Specifications & Trial Overview
| Feature / Metric | ZCode & GLM-5.3 Specification |
|---|---|
| Foundation Model | GLM-5.3 (Zhipu AI / Z.ai) |
| Context Window | 1,000,000 Tokens (1M Native Standard) |
| Trial Allowance | 25 Million Tokens Total (5M/day for 5 days) |
| Daily Quota Split | 3M GLM-5.3 + 2M GLM-5-Turbo Tokens |
| Credit Card Requirement | None |
| CyberGym Security Score | 84.5% (Surpasses Mythos 5 at 83.8%) |
| Terminal Bench 3.0 Score | 28.3% (+515% vs GLM-5.2’s 4.6%) |
| DeepSWE Score | 66.9% |
| AutomationBench Score | 48.2% |
| Supported Platforms | macOS (Apple Silicon & Intel), Windows, Linux |
What Differentiates an Agentic Development Environment (ADE)?
Traditional developer tooling integrates AI as an assistant via inline tab-completions. An ADE places the agent in the executive seat of the development lifecycle:
flowchart TD
    A[Engineer Goal: e.g., 'Migrate Auth to OAuth2 & Fix Tests'] --> B[ZCode ADE Planning Engine]
    B --> C[Analyze Repository AST & Git State]
    C --> D[Multi-File Source Code Editing]
    D --> E[Execute Build & Unit Tests in Sandboxed Terminal]
    E --> F{Compiler / Test Errors?}
    F -->|Errors Detected| G[Parse Stack Trace & Self-Correct]
    G --> D
    F -->|All Tests Pass| H[Headless Browser DOM Verification]
    H --> I[Stage Clean Git Diff for Developer Review]
Core Architectural Features:
- Persistent Execution Loops: Define high-level milestones and let the agent work autonomously through multi-stage dependency upgrades.
- Integrated Sandboxed Terminal: Executes shell commands, resolves missing packages, and parses compiler warnings without copy-pasting back and forth.
- Headless Browser Validation: Inspects frontend DOM changes and console logs to verify that user interface components render as intended.
- Model-Agnostic BYOK Routing: While optimized for GLM-5.3, developers can configure custom API keys for Claude Sonnet 4.6, GPT-5.6 Sol, or local vLLM nodes.
GLM-5.3 Benchmark Analysis: Measuring the Generational Leap
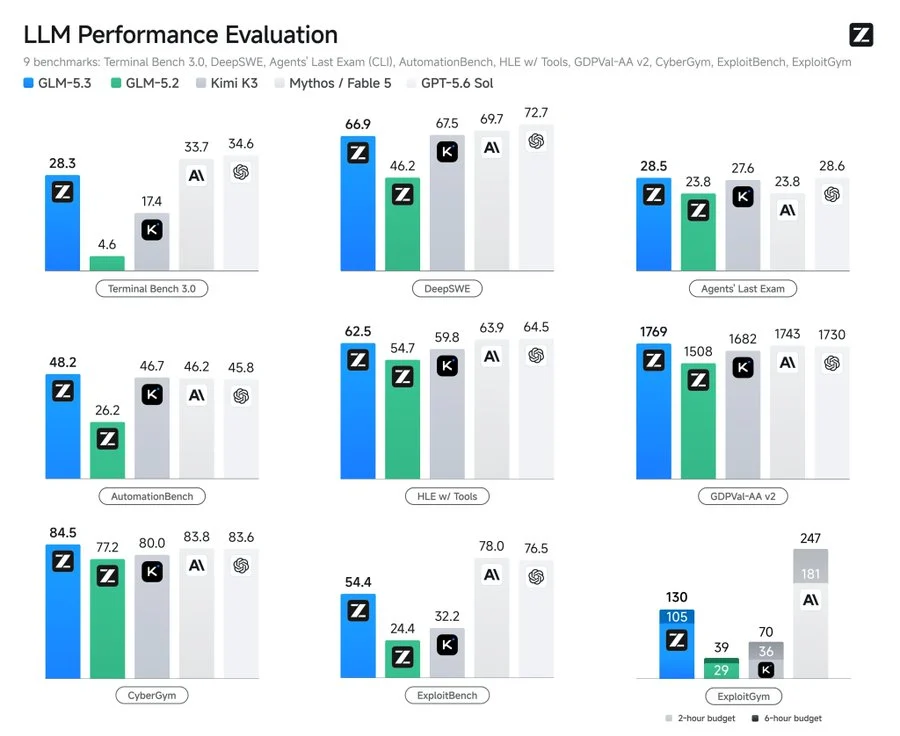
GLM-5.3 represents a comprehensive post-training leap over GLM-5.2, specifically in executable shell environments and security analysis:
Comparative Benchmark Matrix
| Benchmark Suite | GLM-5.3 | GLM-5.2 | Kimi K3 | Anthropic Mythos 5 | GPT-5.6 Sol |
|---|---|---|---|---|---|
| Terminal Bench 3.0 | 28.3% | 4.6% | 17.4% | 33.7% | 34.6% |
| DeepSWE | 66.9% | 46.2% | 67.5% | 69.7% | 72.7% |
| CyberGym | 84.5% | 77.2% | 80.0% | 83.8% | 83.6% |
| AutomationBench | 48.2% | 26.2% | 46.7% | 46.2% | 45.8% |
| ExploitBench | 54.4% | 24.4% | 32.2% | 78.0% | 76.5% |
| GDPval-AA v2 | 1769 | 1508 | 1682 | 1743 | 1730 |
Key Benchmark Observations:
- Terminal Bench 3.0 Progression: GLM-5.3 jumps from 4.6% to 28.3%, representing a +515.2% relative gain in CLI command execution capability.
- Cybersecurity Parity: On CyberGym, GLM-5.3 achieves 84.5%, outperforming both Anthropic Mythos 5 (83.8%) and GPT-5.6 Sol (83.6%) in vulnerability identification and patch generation.
- Software Engineering Parity: At 66.9% on DeepSWE and 48.2% on AutomationBench, GLM-5.3 operates within striking distance of the highest-rated closed proprietary models on our AI Model Leaderboard.
How to Claim the 25 Million Free Trial Tokens
- Download the Desktop Client: Visit the official ZCode Download Portal and download the desktop client for your operating system.
- Account Sign-Up: Launch the application and sign in with your Z.ai credentials.
- Automatic Credit Activation: The 5M daily token allocation activates automatically upon first login, refreshing every 24 hours for 5 days.
- Select GLM-5.3: Choose
GLM-5.3from the model selector in the status bar to ensure your session utilizes the frontier agent model. - Open Repository: Point ZCode to an existing codebase, set a project objective, and review generated diffs before committing.
Related Developer Offers & Tool Comparisons
Explore how ZCode compares to alternative coding environments and credit programs:
- Zed Pro 14-Day Free Trial: $20 in hosted model credits covering multiple model providers inside a high-speed Rust editor.
- Fireworks AI $6 Free Credits: Up to 214M tokens of DeepSeek V4 Flash for testing terminal agent workflows.
- Coding Plans & Subscriptions Matrix: Deep pricing and rate limit analysis covering 50+ developer subscription tiers.
- SWE-bench Pro Guide: How frontier models are benchmarked on real-world multi-file software engineering tasks.
RankLLMs Technical Verdict
ZCode represents an impressive union of frontier foundation model capabilities and autonomous software engineering ergonomics.
With 25M free trial tokens, 1M native context, and state-of-the-art 84.5% CyberGym performance, GLM-5.3 inside ZCode offers a compelling alternative to proprietary American coding ecosystems for engineers building and refactoring complex software systems.
Benchmark and pricing data is aggregated from OpenRouter, Artificial Analysis, and models.dev, then scored with the published RankLLMs Index. These are the primary sources behind the numbers in this article.
- •Z.ai: ZCode Desktop ADE Launch Documentation(Primary Source →)
- •Zhipu AI: GLM-5.3 Frontier Model Technical Specifications(Primary Source →)
- •Reuters: Z.ai Says New Model Nears Anthropic Mythos in Cyber Defence(Primary Source →)
Lucky Yaduvanshi(luckyyaduvanshi.in →)
Founder of RankLLMs • AI Researcher & Software Engineer focusing on LLM benchmarking, DevOps, and autonomous coding agents.
Recommended Reading
Continue exploring related technical benchmarks, model deep-dives, and autonomous coding agent guides.
GLM-5.3 in ZCode: Agentic Coding Integration and Evaluation
Z.ai rolled out GLM-5.3 to all ZCode users with free tier access, reset quotas, and top scores on CyberGym (84.5%), GDPval-AA, and Terminal-Bench 2.1 (88.2).
Lucky Yaduvanshi
GLM-5.3-FlashX: 200 Tokens/sec Throughput vs 2.5x Price Analysis
In-depth review of GLM-5.3-FlashX: 200 tokens/second inference throughput, latency benchmarks, and whether the 2.5x pricing premium is justified.
Lucky Yaduvanshi
TypeSafe AI Jev Access Guide: Free Trial Endpoints, API Pricing, and System One Architecture
How to access TypeSafe AI's Jev model for free: Vercel AI Gateway promotion, OpenRouter pricing at $0.042/1M tokens, latency benchmarks, and System One design.
Lucky YaduvanshiTypeSafe AI Jev Architectural Deep Dive: System One Decision Models vs Generative LLMs
Why TypeSafe AI's Jev model captured 13% of Vercel AI Gateway teams in 24 hours. Deep dive into RLCD training, 70ms decision latency, and architecture.
Lucky Yaduvanshi