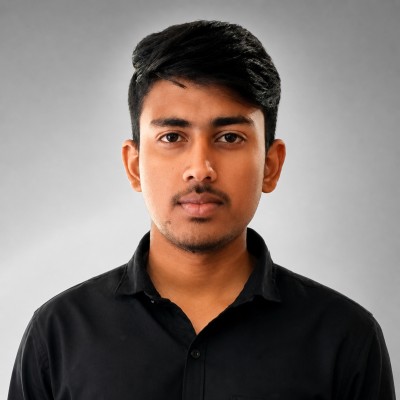
Founder & Editor
Lucky Yaduvanshi
I am a software engineer and DevOps specialist, and I founded RankLLMs to make AI model comparisons easier to inspect. I lead its research and editorial work. Benchmark results are attributed to their sources, and model specifications or prices may be updated through an automated sync before editorial review.
What I do at RankLLMs
- 01
Maintain the scorecards
RankLLMs tracks 95 models. Benchmark inputs and model specifications come from identified sources; a daily workflow proposes metadata and pricing changes while preserving benchmark score fields and editorial text.
- 02
Review coding tools
When a review includes hands-on testing, the page should describe the task, environment, and observed results separately from vendor claims and external benchmark data.
- 03
Review source changes
Automated syncs create proposed updates for model specifications and pricing. Benchmark data is preserved during those syncs, and published values should be read with their source, model version, and date.
- 04
Write and edit analysis
Comparisons and reviews interpret the available evidence for a reader's use case. Published benchmark results are credited to their provider or evaluator and are not presented as hands-on tests unless the page documents one.
How my work is verified
The methodology page documents the composite formula, update workflow, and limits of the data. The editorial policy explains how source-backed corrections are reviewed and marked.
Independence
RankLLMs is not owned by an AI provider, and model vendors cannot purchase scores or placement on the leaderboard. The Site carries Google AdSense ads and may use affiliate or referral links; those relationships are disclosed near relevant content and do not determine research conclusions.
Latest articles
View all (40) →

Publishing on RankLLMs since August 2026 • Questions or corrections? Get in touch.