Sourced AI Benchmarks • Last checked Oct 15, 2026
About RankLLMs
Meet the independent AI research publication behind RankLLMs, its founder, and the methods used to compare models.
Our Mission: Transparent, Independent AI Benchmarks
RankLLMs helps developers compare AI models and software tools using sourced benchmark signals, capability scores, published pricing and speed data, and editorial reviews. It is an independent publication, not a model provider. The goal is to show how a comparison was reached, where its evidence came from, and what the data cannot tell you.
What We Benchmark & Evaluate
RankLLMs combines benchmark results published by providers and independent evaluators with model specifications and editorial analysis. We do not claim to rerun every third-party evaluation ourselves. The directory helps readers compare:
- 01
Software engineering
Coding scores and software engineering benchmark results, with the source and test context kept in view.
- 02
Reasoning and knowledge
Reasoning and knowledge scores assembled from named evaluation sources.
- 03
Agent and tool use
Agent and tool-use signals, treated as a starting point rather than a guarantee for every workflow.
- 04
Speed and latency
Published throughput and latency measurements, which vary with provider, region, load, and test setup.
- 05
Price and deployment
Listed API pricing, context limits, and open-weight status; confirm current terms with the provider.
- 06
Editorial reviews and guides
Human-written comparisons and software reviews, separated from sourced benchmark scores.
How We Work
A GitHub Actions workflow checks model specifications and pricing once a day using models.dev and OpenCode, then opens a pull request for review. That sync preserves the benchmark score fields and editorial analysis; a metadata refresh is not a new benchmark test. Our methodology page explains the composite score, data sources, and limitations.
The rankllms-engine source repository is published under the MIT license for inspection and reuse. The source code makes the scoring logic easier to examine; it does not mean RankLLMs independently reruns every benchmark reported on the Site.
Our editorial policy covers sourcing rules, corrections, and how AI tools are (and are not) used in production. It explains how claims are sourced, how verified material corrections are dated, and why vendors cannot buy a ranking or review outcome.
Independence & Funding
RankLLMs is independently operated and is not owned by an AI model provider. Providers cannot purchase scores, rankings, or review outcomes. The Site currently loads Google AdSense advertising. Some editorial links may also be affiliate or referral links; any material relationship is disclosed near the relevant recommendation or link. Advertising and referral revenue do not determine scores or verdicts. See the editorial policy and disclaimer.
Found a bug in our data, or represent a lab with newer official results? We verify and correct in public - reach us through the contact page.
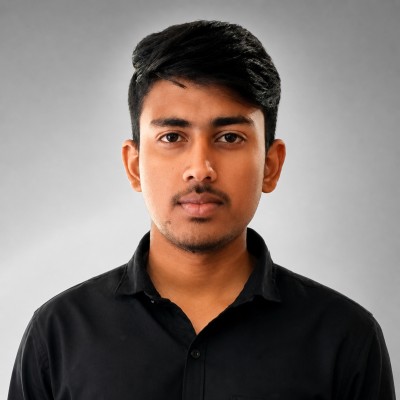
Founded by Lucky Yaduvanshi
Lucky Yaduvanshi is the founder and editor of RankLLMs. His work focuses on software engineering, DevOps, AI model evaluation, and the practical trade-offs between capability, speed, and price. He maintains the site's scoring approach and reviews its editorial conclusions; automated metadata updates and third-party benchmark results are identified separately from hands-on testing.