Sourced AI Benchmarks • Last checked Oct 15, 2026
RankLLMs Research Author
Meet Lucky Yaduvanshi, the founder and editor responsible for RankLLMs model research and editorial analysis.
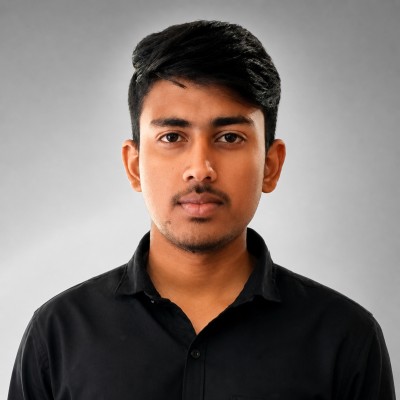
Founder & Editor
Lucky Yaduvanshi
40 articles published • 95 models tracked • one named editor accountable for published analysis
Software engineer and AI performance researcher focusing on LLM latency, cost efficiency, SWE-bench coding benchmarks, and autonomous agent evaluation.
Why one author
RankLLMs is currently an independent publication with one named founder and editor. That makes ownership and responsibility easy to identify; it does not mean every benchmark is run in-house. We distinguish sourced results from hands-on testing and explain corrections in the editorial policy.
The work is supported by a published scoring methodology, a traceable model directory, and an interactive leaderboard. The methodology also explains where automation is used and which limitations remain.
Editorial standards
- Source-aware data
- Scorecards separate sourced benchmark results from product specifications; the methodology explains their sources and update path.
- Named sources
- Benchmark and product information is attributed to the provider or evaluator where available.
- Disclosed costs
- Where RankLLMs estimates task cost, the calculation states its workload assumptions.
- Independence
- Vendors cannot buy scores or placement; advertising and affiliate relationships are disclosed.
- Public corrections
- Verified material corrections are dated on the affected page; report source-backed errors through the contact page.
- Testing disclosure
- First-party tests are distinguished from external benchmark results and vendor claims.
Most recent publication: Claude Code vs Gemini CLI vs GitHub Copilot CLI (2026 Tested). To suggest a correction or comparison, contact the editor.