AMD AI Developer Program: $50 Fireworks AI Serverless Credit Evaluation and Token Economics
Claim $50 in Fireworks AI credits via the AMD AI Developer Program. Token yield analysis across DeepSeek V4 Pro, MiniMax M3, GLM-5.3, and 90-day terms.
Synthesizing article benchmarks & model metrics...
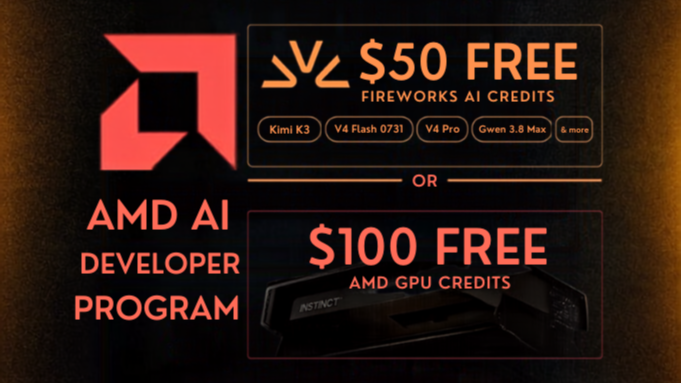
The AMD AI Developer Program provides approved software engineers and machine learning practitioners with a $50 promotional grant for Fireworks AI, unlocking serverless access to leading open-weight frontier models without upfront expenditure.
Unlike short-duration introductory coupons, AMD’s program delivers an enterprise-grade perk package: developers can choose between $50 in Fireworks AI API credits or $100 in AMD Developer Cloud compute, alongside a complimentary one-month membership to DeepLearning.AI.
For developers optimizing agentic pipelines and evaluating model cost efficiency, this $50 allocation represents substantial inference capacity.
Program Summary & Core Specifications
| Feature | AMD Program Specification |
|---|---|
| Primary Cloud Credit | $50 Fireworks AI Serverless Credit |
| Alternative Infrastructure Perk | $100 AMD Developer Cloud Instances |
| Redemption Window | 90 Calendar Days from Issuance |
| Eligible Models | DeepSeek V4 Flash, DeepSeek V4 Pro, MiniMax M3, Kimi K3 |
| Credit Card Requirement | Optional (10 RPM unverified / 6,000 RPM verified) |
| Educational Perks | 1 Month DeepLearning.AI Membership + AMD AI Academy |
| SDK Standard | OpenAI & Anthropic Wire Compatible |
Model Purchasing Power: What Does $50 Buy on Fireworks AI?
Because Fireworks prices serverless models on dynamic token usage with steep prompt-caching discounts, a $50 credit produces vast variations in effective token volume depending on the chosen model:
| Model | Input Rate / 1M | Cached Input / 1M | Output Rate / 1M | Max Cached Token Yield ($50) | Max Uncached Token Yield ($50) |
|---|---|---|---|---|---|
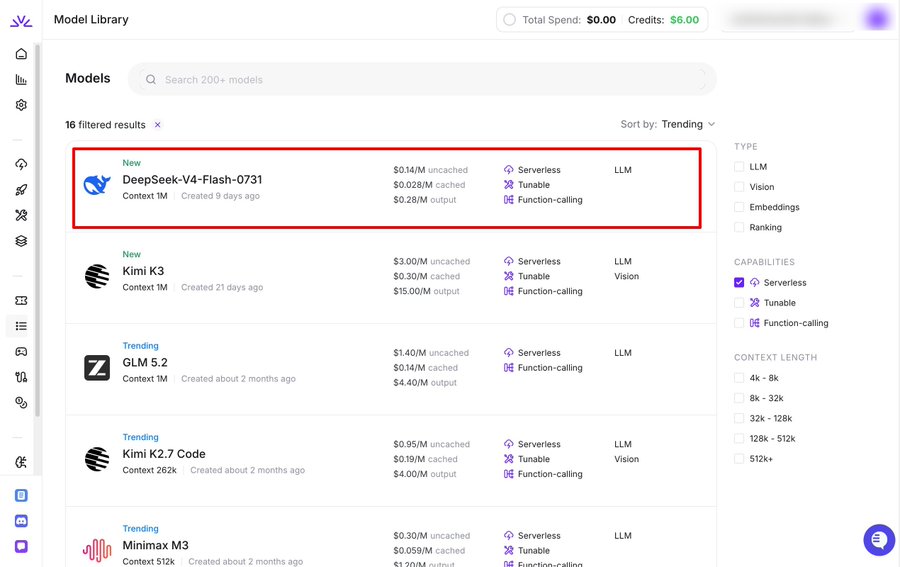
| DeepSeek V4 Flash | $0.14 | $0.028 | $0.28 | 1,785,714,000 (~1.79B) | 357,142,000 (~357M) |
| MiniMax M3 | $0.30 | $0.059 | $1.20 | 847,457,000 (~847M) | 166,666,000 (~167M) |
| DeepSeek V4 Pro 0813 | $1.74 | $0.145 | $3.48 | 344,827,000 (~345M) | 28,735,000 (~28.7M) |
| GLM 5.2 | $1.40 | $0.140 | $4.40 | 357,142,000 (~357M) | 35,714,000 (~35.7M) |
| Kimi K3 | $3.00 | $0.300 | $15.00 | 166,666,000 (~167M) | 16,666,000 (~16.7M) |
Key Economic Takeaways:
- High-Throughput Extraction & Routing: On DeepSeek V4 Flash, $50 allows developers to process nearly 1.8 billion cached tokens, making it ideal for massive vector indexing or document classification workloads.
- Autonomous Coding Agent Workloads: On DeepSeek V4 Pro 0813, $50 funds over 340 million cached context tokens, enabling hundreds of comprehensive SWE-bench bug-fixing runs.
- Reasoning Benchmarking: Running complex multi-step evaluations on Kimi K3 yields up to 166M cached tokens, sufficient to benchmark production prompts against proprietary models like Claude Sonnet 4.6.
Step-by-Step Guide to Claiming the $50 Credit
To access the AMD perk and apply it to your Fireworks billing profile:
flowchart LR
    A[AMD Developer Portal] -->|Register Profile| B[Select Member Perks]
    B -->|Choose Fireworks $50| C[Application Review ~48h]
    C -->|Email Promo Code| D[Fireworks Billing Console]
    D -->|Redeem Voucher| E[$50 Serverless Balance]
- Create an AMD Developer Account: Register at AMD Developer Central using your GitHub or business profile.
- Access Member Benefits: Navigate to the
AI Developer Programdashboard and locate theCloud Compute & Inference Creditssection. - Select Fireworks AI Perk: Choose the $50 Fireworks AI Credit option (note that choosing this option supersedes the AMD Developer Cloud $100 compute credit).
- Submit Application: Fill out the brief application detailing your current AI development or research focus. Applications are typically approved within two business days.
- Redeem Promo Code: Copy the unique promotional code sent via email, log in to your Fireworks AI Account, navigate to
Settings→Billing, and enter the voucher in the promo code redemption field. - Track Validity: Ensure the code is redeemed within 90 calendar days of receipt. Once added to Fireworks, the balance remains active until fully depleted.
Unverified vs Verified Account Rate Limits
When testing models on Fireworks without attaching a credit card, accounts operate under an account-wide limit of 10 requests per minute (RPM).
While 10 RPM is adequate for single-turn interactive debugging or evaluating individual prompts in a Jupyter notebook, autonomous coding loops (such as Muse Code or SWE-bench benchmarks) require continuous tool calling. Adding a payment method lifts the ceiling to 6,000 RPM while ensuring that all token consumption continues to debit from your $50 promotional credit first before charging your card.
Technical Integration with Open-Source Harnesses
Fireworks supports OpenAI-compatible REST endpoints. You can query models directly through the official OpenAI Python SDK:
from openai import OpenAI
client = OpenAI(    base_url="https://api.fireworks.ai/inference/v1",    api_key="YOUR_FIREWORKS_API_KEY",)
response = client.chat.completions.create(    model="accounts/fireworks/models/deepseek-v4-pro-0813",    messages=[        {"role": "system", "content": "You are an expert systems software engineer."},        {"role": "user", "content": "Analyze memory leaks in this Rust async runtime trace."},    ],    temperature=0.2,)
print(response.choices[0].message.content)
Related Developer Offers & Comparative Value
Compare AMD’s promotional offering with other developer sandbox programs:
- Fireworks AI $6 Onboarding Credits: Instant promotional credits for new accounts without application wait times.
- Zed Pro 14-Day Free Trial: $20 in hosted credits covering Claude Sonnet, GPT-5.6, and Gemini 3.1 Pro inside a native Rust editor.
- ZCode GLM-5.3 25M Token Trial: Dedicated desktop Agentic Development Environment with 1M context.
- AI Model Leaderboard: Comprehensive real-time accuracy, latency, and pricing data across 85+ LLMs.
RankLLMs Verdict
The AMD AI Developer Program’s $50 Fireworks AI grant is an exceptional developer asset.
By pairing AMD’s sponsorship with Fireworks’ competitive MoE hosting rates, engineers receive enough inference volume to conduct statistically meaningful benchmark comparisons, validate long-context retrieval architectures, and power automated coding workflows across DeepSeek V4 Pro and MiniMax M3 without infrastructure overhead.
RankLLMs independent evaluations verify official benchmarks against reproducible testing suites, community logs, and provider documentation.
- •AMD Developer Central: AI Developer Program(Primary Source →)
- •Fireworks AI Documentation & Model Catalog(Primary Source →)
- •DeepLearning.AI Partnership Announcement(Primary Source →)
Was this benchmark analysis helpful?
Thank you for your feedback! We update our benchmarks weekly based on developer input.
Lucky Yaduvanshi(luckyyaduvanshi.in →)
Founder of RankLLMs • AI Researcher & Software Engineer focusing on LLM benchmarking, DevOps, and autonomous coding agents.
Recommended Reading
Continue exploring related technical benchmarks, model deep-dives, and autonomous coding agent guides.
Fireworks AI Developer Free Credits: $6 Promotional Balance and DeepSeek V4 Flash Economics
Analysis of Fireworks AI promotional credits: $6 onboarding balance, 214M+ DeepSeek V4 Flash cached tokens, API rate limits, and Claude Code setup.
Lucky Yaduvanshi
Best LLMs for Coding in 2026: SWE-bench Verified Data & Cost Math
The best coding LLMs in 2026, ranked by SWE-bench Verified, Terminal Bench, and cost per solved task. Claude Fable 5 leads raw accuracy; Gemini 3.7 Flash and GLM-5.3-Flash lead value.
Lucky Yaduvanshi
GLM-5.3-FlashX: 200 Tokens/sec Throughput vs 2.5x Price Analysis
In-depth review of GLM-5.3-FlashX: 200 tokens/second inference throughput, latency benchmarks, and whether the 2.5x pricing premium is justified.
Lucky YaduvanshiTypeSafe AI Jev Access Guide: Free Trial Endpoints, API Pricing, and System One Architecture
How to access TypeSafe AI's Jev model for free: Vercel AI Gateway promotion, OpenRouter pricing at $0.042/1M tokens, latency benchmarks, and System One design.
Lucky Yaduvanshi